About01Work02Stack03Experience04FAQ05
zakria@zaktecs.devLinkedIn ↗GitHub ↗

Portfolio 2026

Available for work

I turn websitesinto cleanstructured data.

I scrape sites, clean the mess, and put it in a sheet that updates itself.

269k+Records scraped
186kLeads verified
12Live projects
Lahore, Pakistan · --:-- PKTGitHub ↗

01 — About

I get data out of the web, and make it usable.

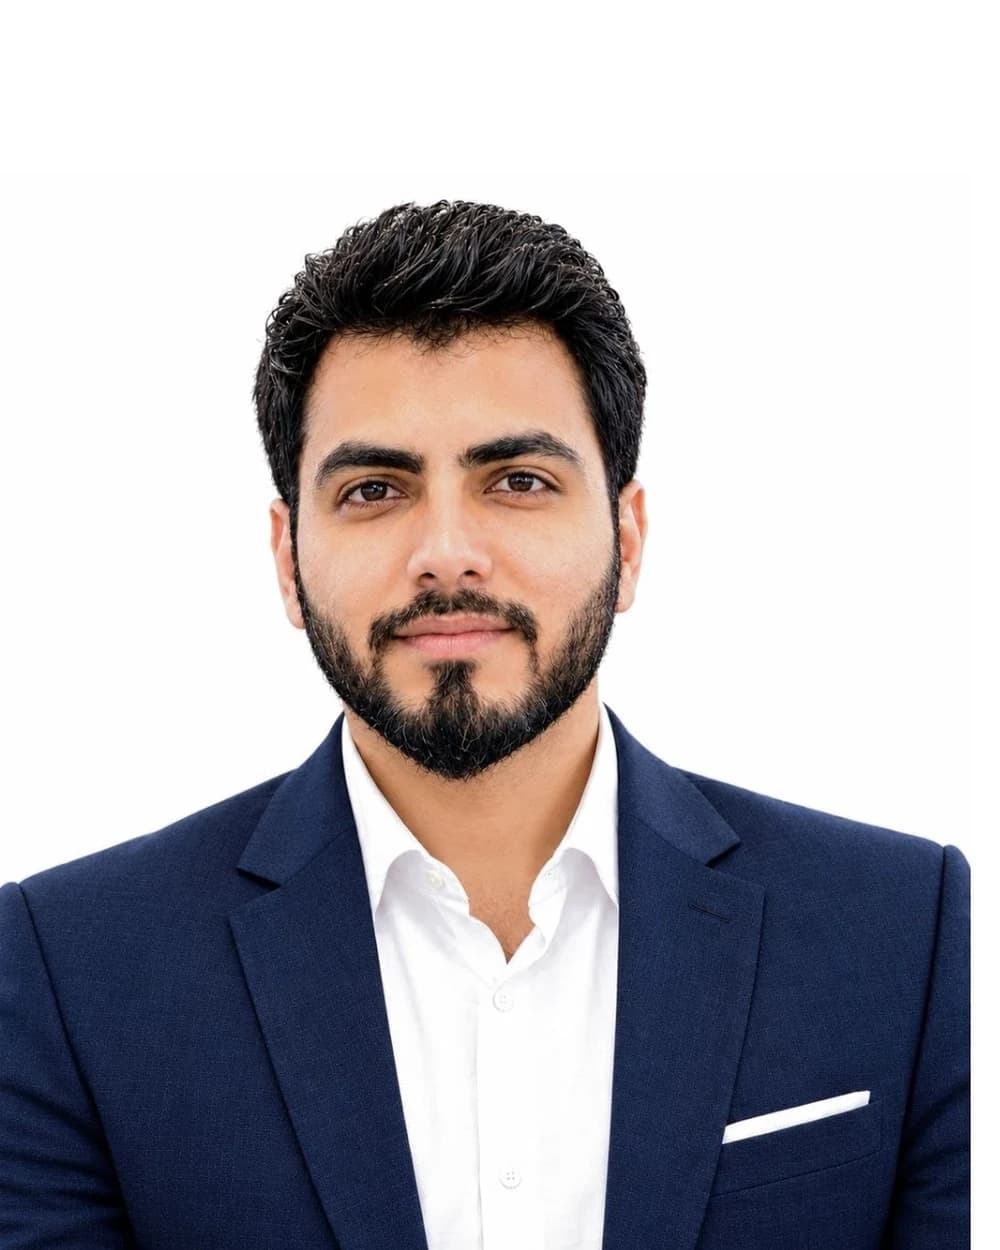
Portrait of Muhammad Zakria
Muhammad ZakriaLahore, Pakistan
Available

I'm Zakria, a web scraper and data analyst in Lahore. I take data stuck inside websites and turn it into clean spreadsheets your team can use.

  • ScrapeJS-heavy sites, logins, pagination, anti-bot.
  • CleanDedupe, normalise, verify emails before delivery.
  • AutomateScheduled runs refresh your sheet on their own.

Most work is white-label for agencies. I also keep the boring parts running: retries, checkpoints, run reports.

02 — Selected work

Twelve builds, 269k rows.

Open a card for the method, the numbers and the repo.

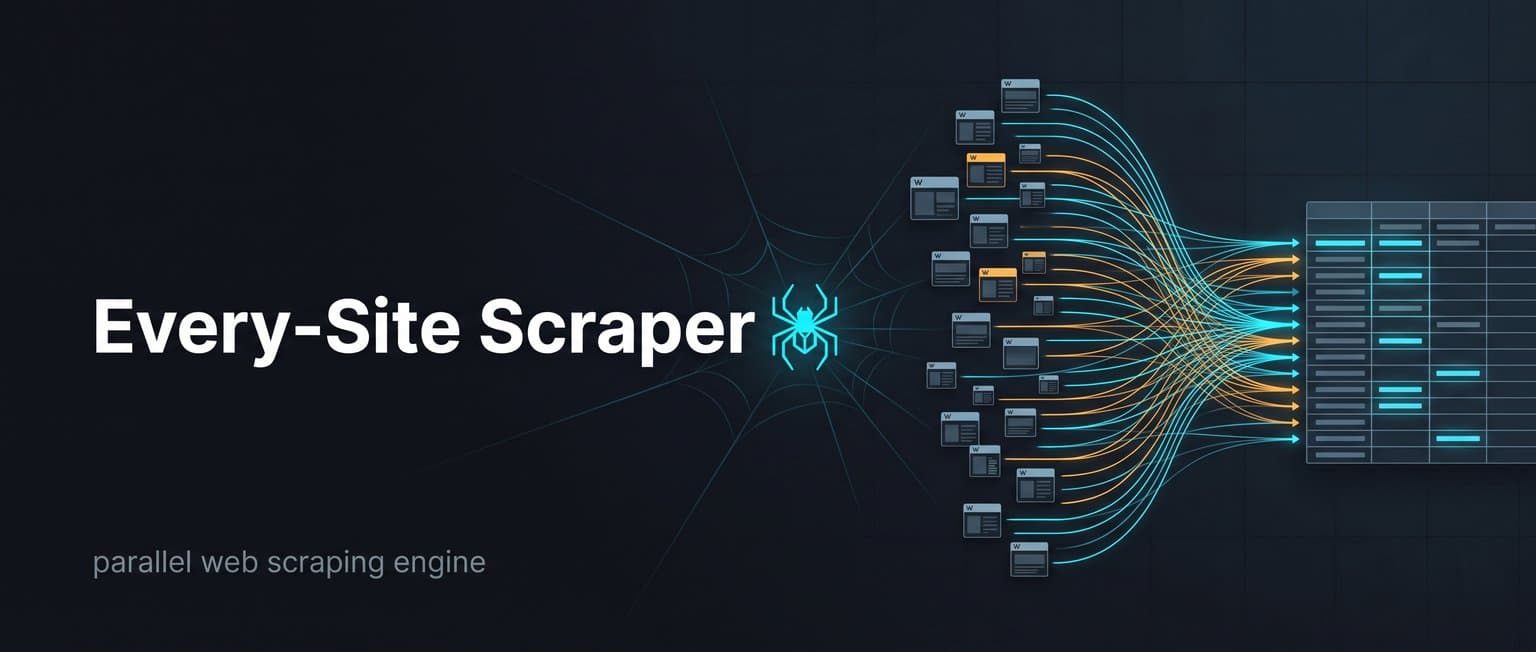
Every-Site Scraping — Open Source project
Open Source
Project 012026

Every-Site Scraping

Open-source CLI — any URL list to 90 columns

A parallel scraper and crawler: paste URLs, get one row per page across a fixed 90-column schema — SEO, contacts, socials, tech stack.

90Columns
163Tests
900+Sites validated
MITLicence
PythonBeautifulSouplxmlrequests
GitHub ↗
Google Maps Lead Engine — Open Source project
Open Source
Project 022026

Google Maps Lead Engine

Local businesses to enriched CSV and Excel

Searches Maps for any niche and city, opens every listing, then visits each business site for emails, socials and tech stack.

50States
12Niches
27Fields per row
100%Source-traced
PythonPlaywrightGoogle MapsPandas
GitHub ↗
Zillow Agent Scraper — Open Source project
Open Source
Project 032026

Zillow Agent Scraper

1,500 agents with verified phone numbers

Real-estate agents from Zillow's reviews directory with verified phones. One HTTP request per page, no browser, no CAPTCHA solving.

1,500Agents
100%Valid phones
4Extraction layers
25+Cities per sweep
PythonrequestsPandas
GitHub ↗
Facebook Comment Extractor — Open Source project
Open Source
Project 042026

Facebook Comment Extractor

Public posts, no login, CSV and JSON out

Paste a public post URL, get structured comments. No account, no cookies, no API key — it reads what the logged-out site already ships.

0Logins needed
3Extraction layers
2Output formats
2GitHub stars
PythonrequestsJSON
GitHub ↗
Lahore Data Job Alerts — Automation project
Automation
Project 052026

Lahore Data Job Alerts

253 career pages, emailed every 8 hours

Scrapes 253 verified Lahore career pages, keeps only entry-level data roles, and emails new matches every eight hours.

253Career pages
33Tests
8hCron cycle
0Duplicate alerts
PythonaiohttpLinuxCron
GitHub ↗
Data Automation Toolkit — Open Source project
Open Source
Project 062026

Data Automation Toolkit

15 tools for people who don't code

Fifteen small programs for non-technical users: pull a table into Excel, merge 30 sheets, verify emails, send per-client reports.

15Tools
1Command
3Platforms
MITLicence
PythonPandasopenpyxl
GitHub ↗
AliExpress Product Scraper — Client Work project
Client Work
Project 072026

AliExpress Product Scraper

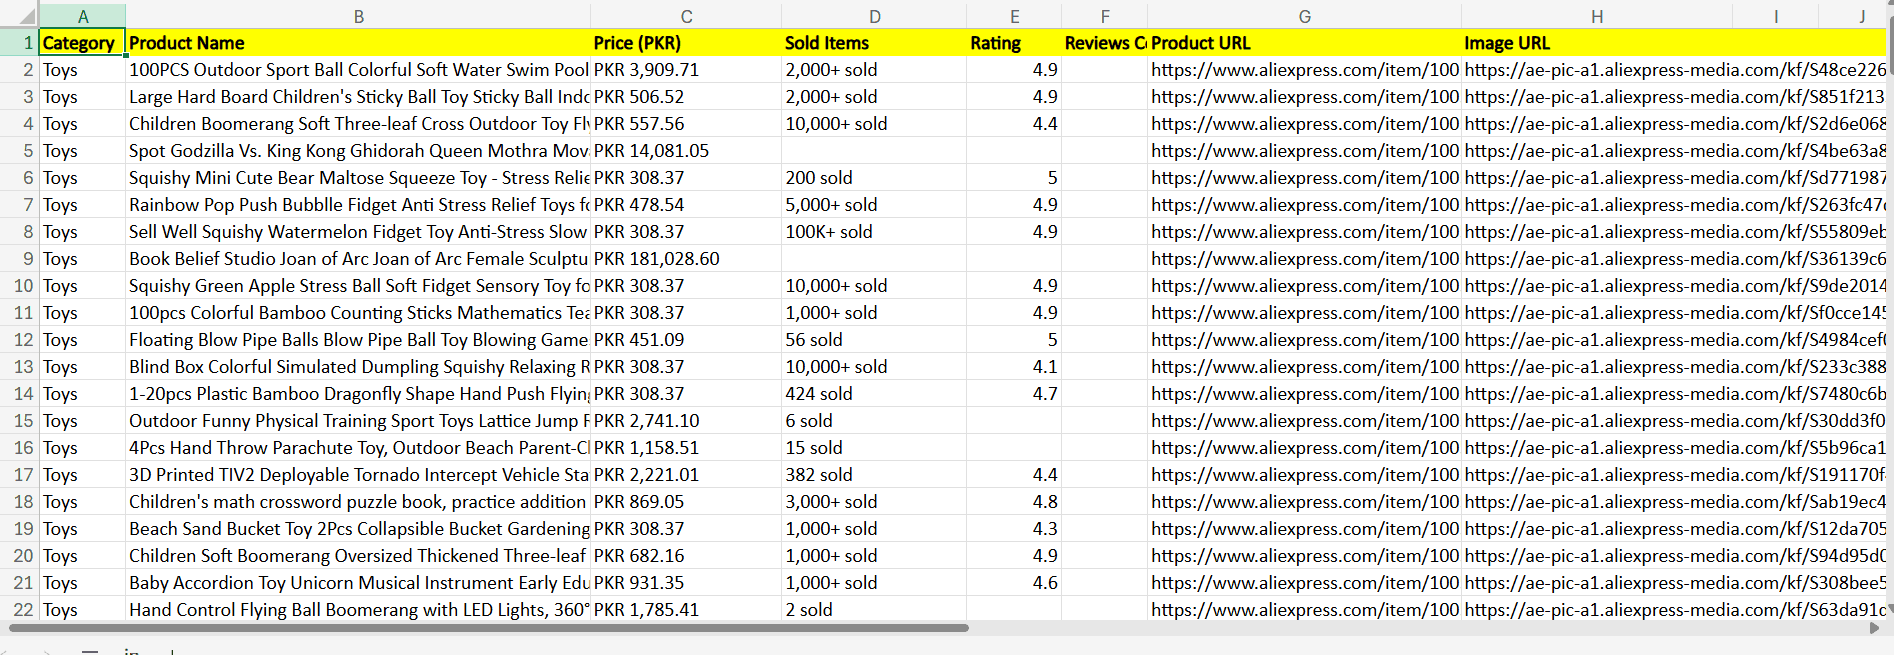
Catalog, price and sales data in one sheet

Category sweeps across AliExpress: product name, price, sold count, rating and image links, written to one spreadsheet per run.

10Categories per run
8Fields per product
1Sheet per run
0Manual copy-paste
PythonSeleniumPandasopenpyxl
Daraz Catalog Scraper — Client Work project
Client Work
Project 082026

Daraz Catalog Scraper

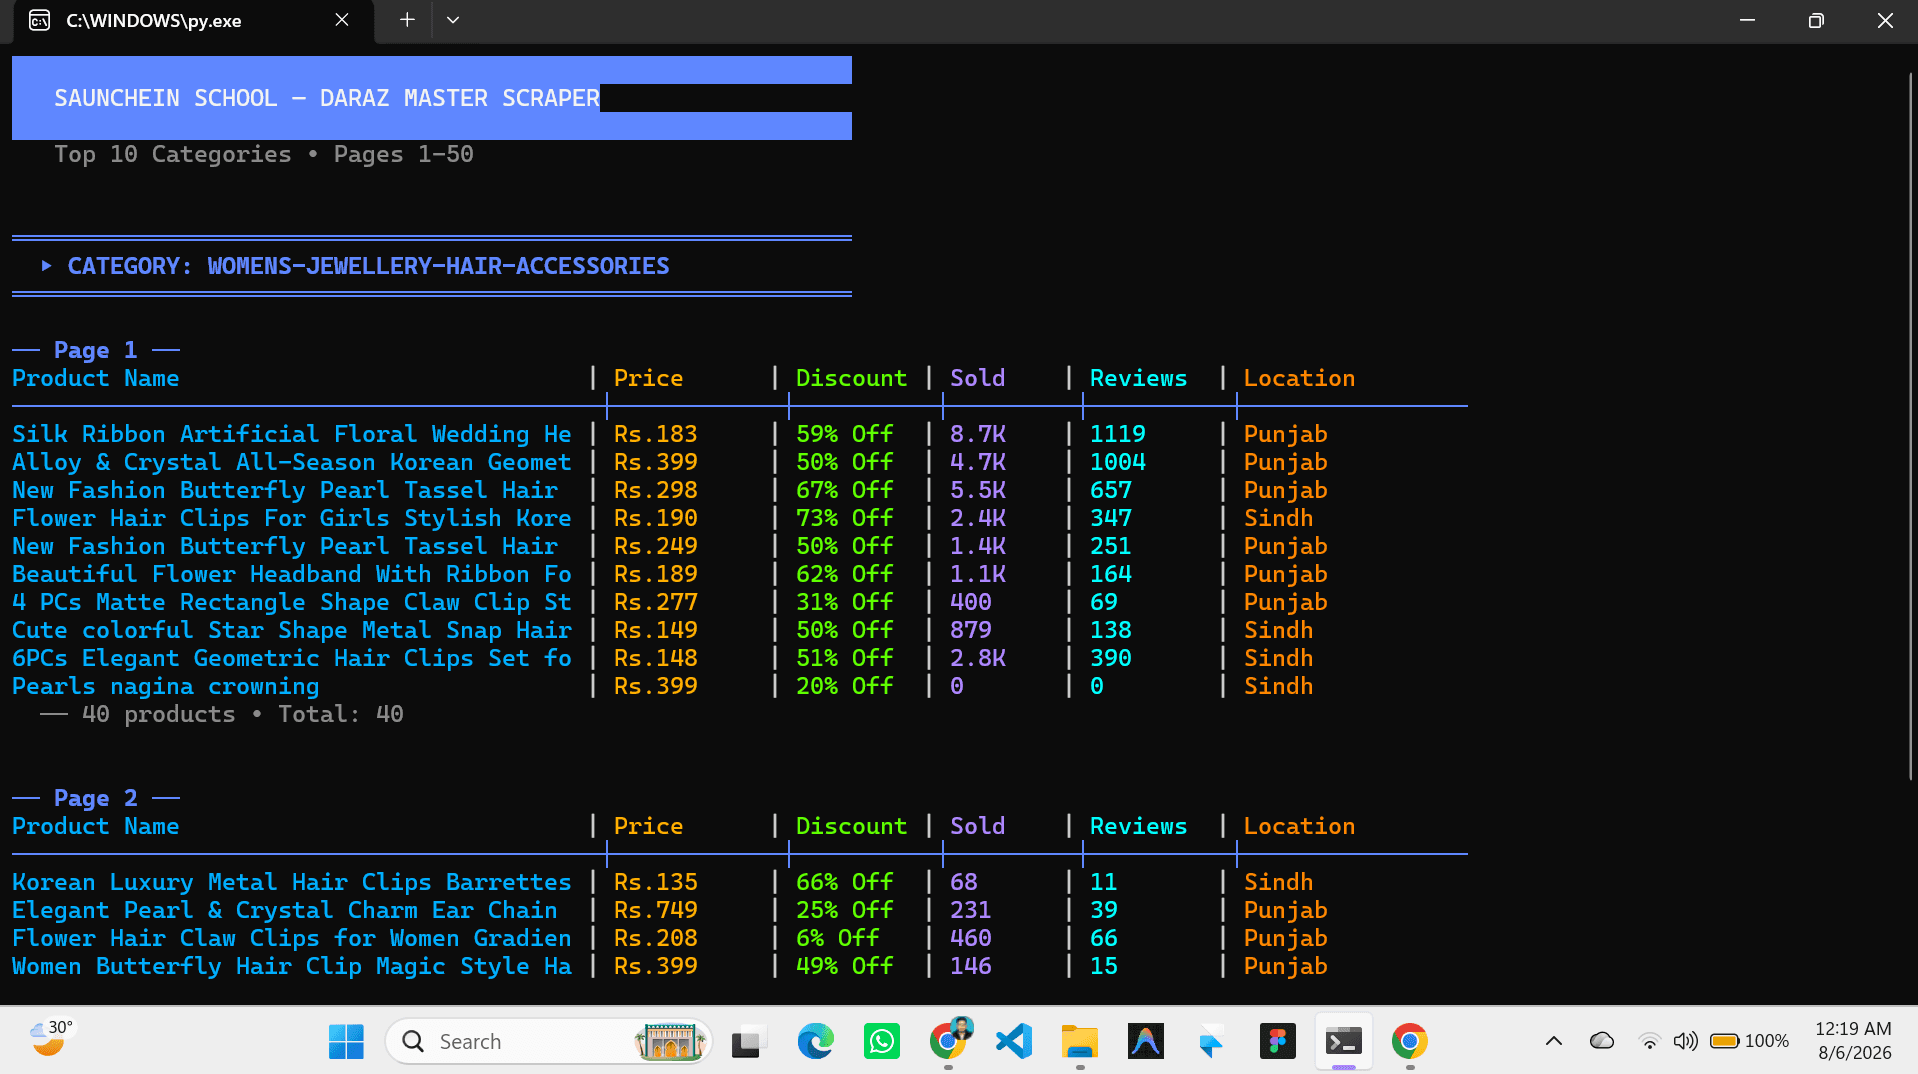
Top categories to one master sheet

Playwright walks the top ten Daraz categories page by page, capturing price, discount, sold count and location into a master dataset.

10Categories
50Pages each
1Master sheet
LiveProgress log
PythonPlaywrightPandasExcel
Funda.nl Listings Scraper — Client Work project
Client Work
Project 092026

Funda.nl Listings Scraper

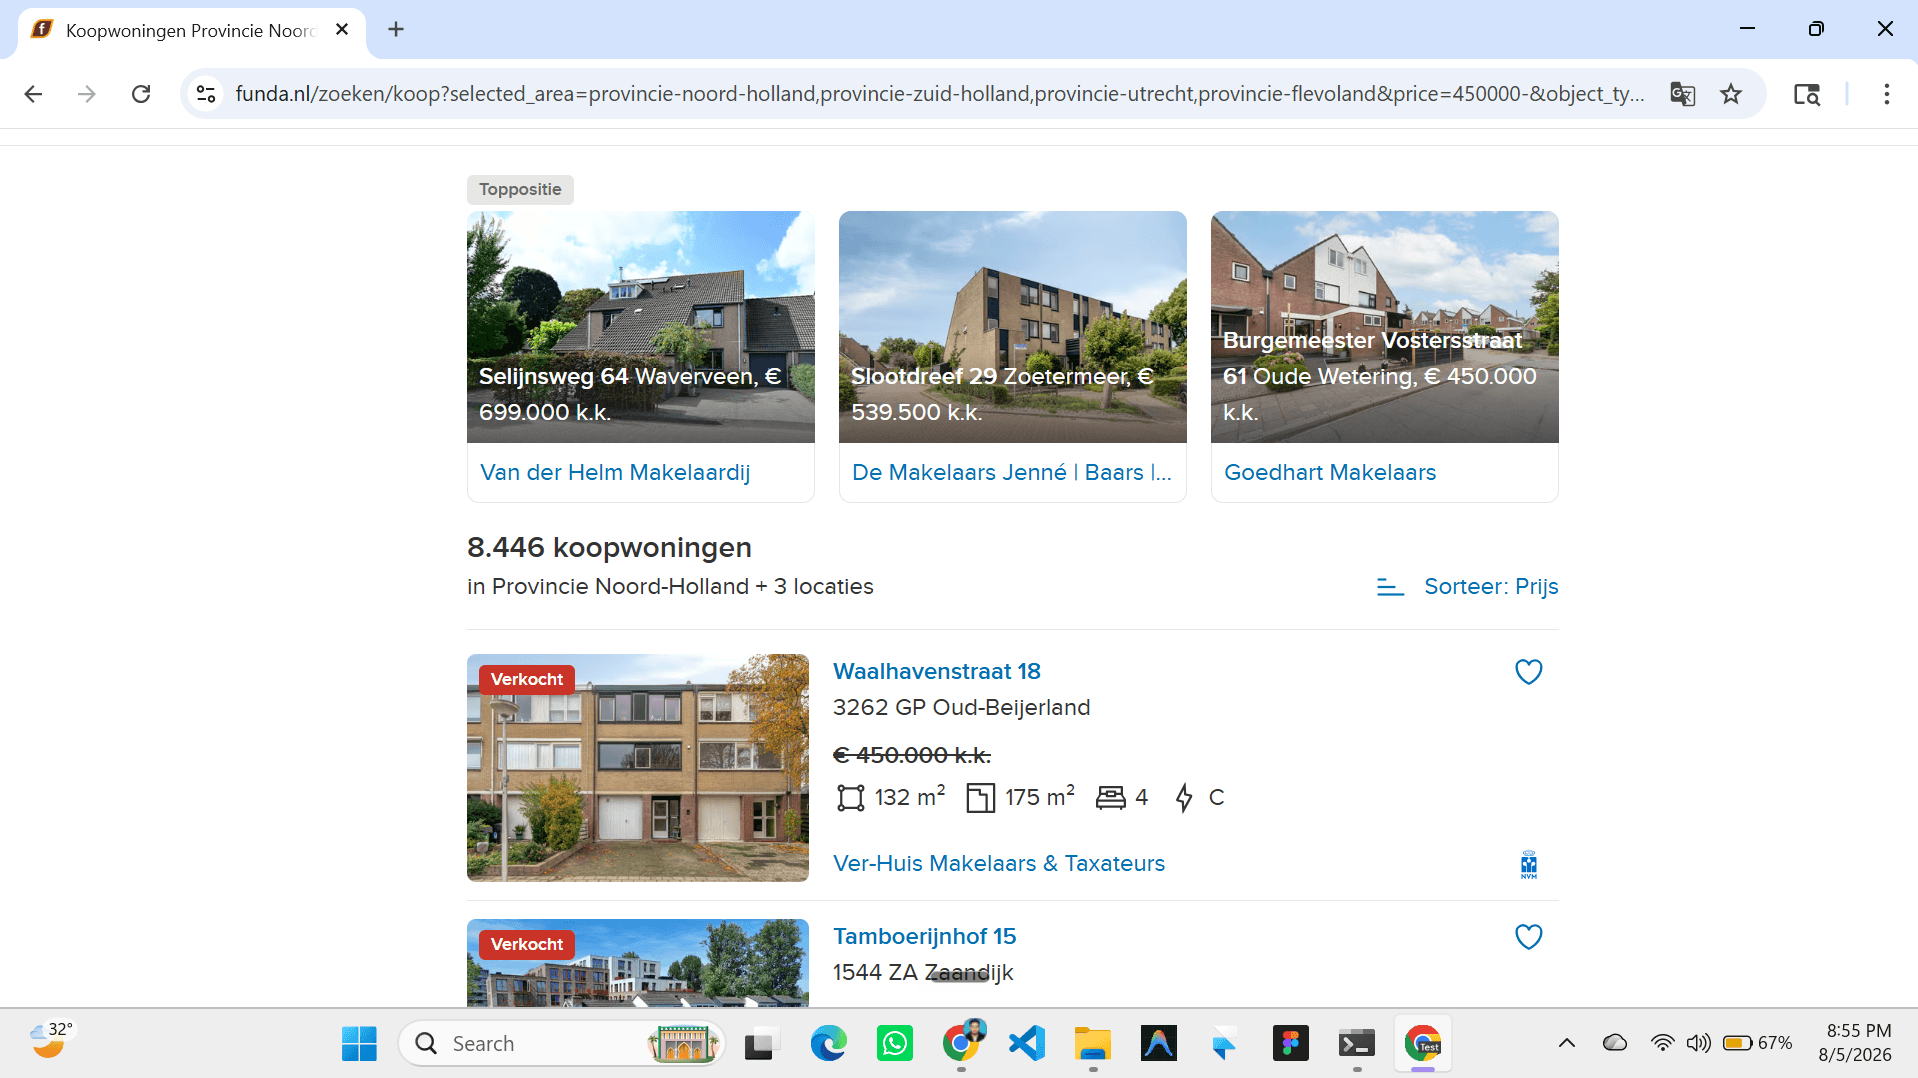
Dutch property listings into a clean master file

Sweeps Funda search results by province and price band, capturing address, price, living area, rooms, energy label and agent.

4Provinces per pass
8+Filters per run
1Master CSV
LiveListing sync
PythonPlaywrightCSVLibreOffice
Multi-Niche B2B Engine — Client Work project
Client Work
Project 102026

Multi-Niche B2B Engine

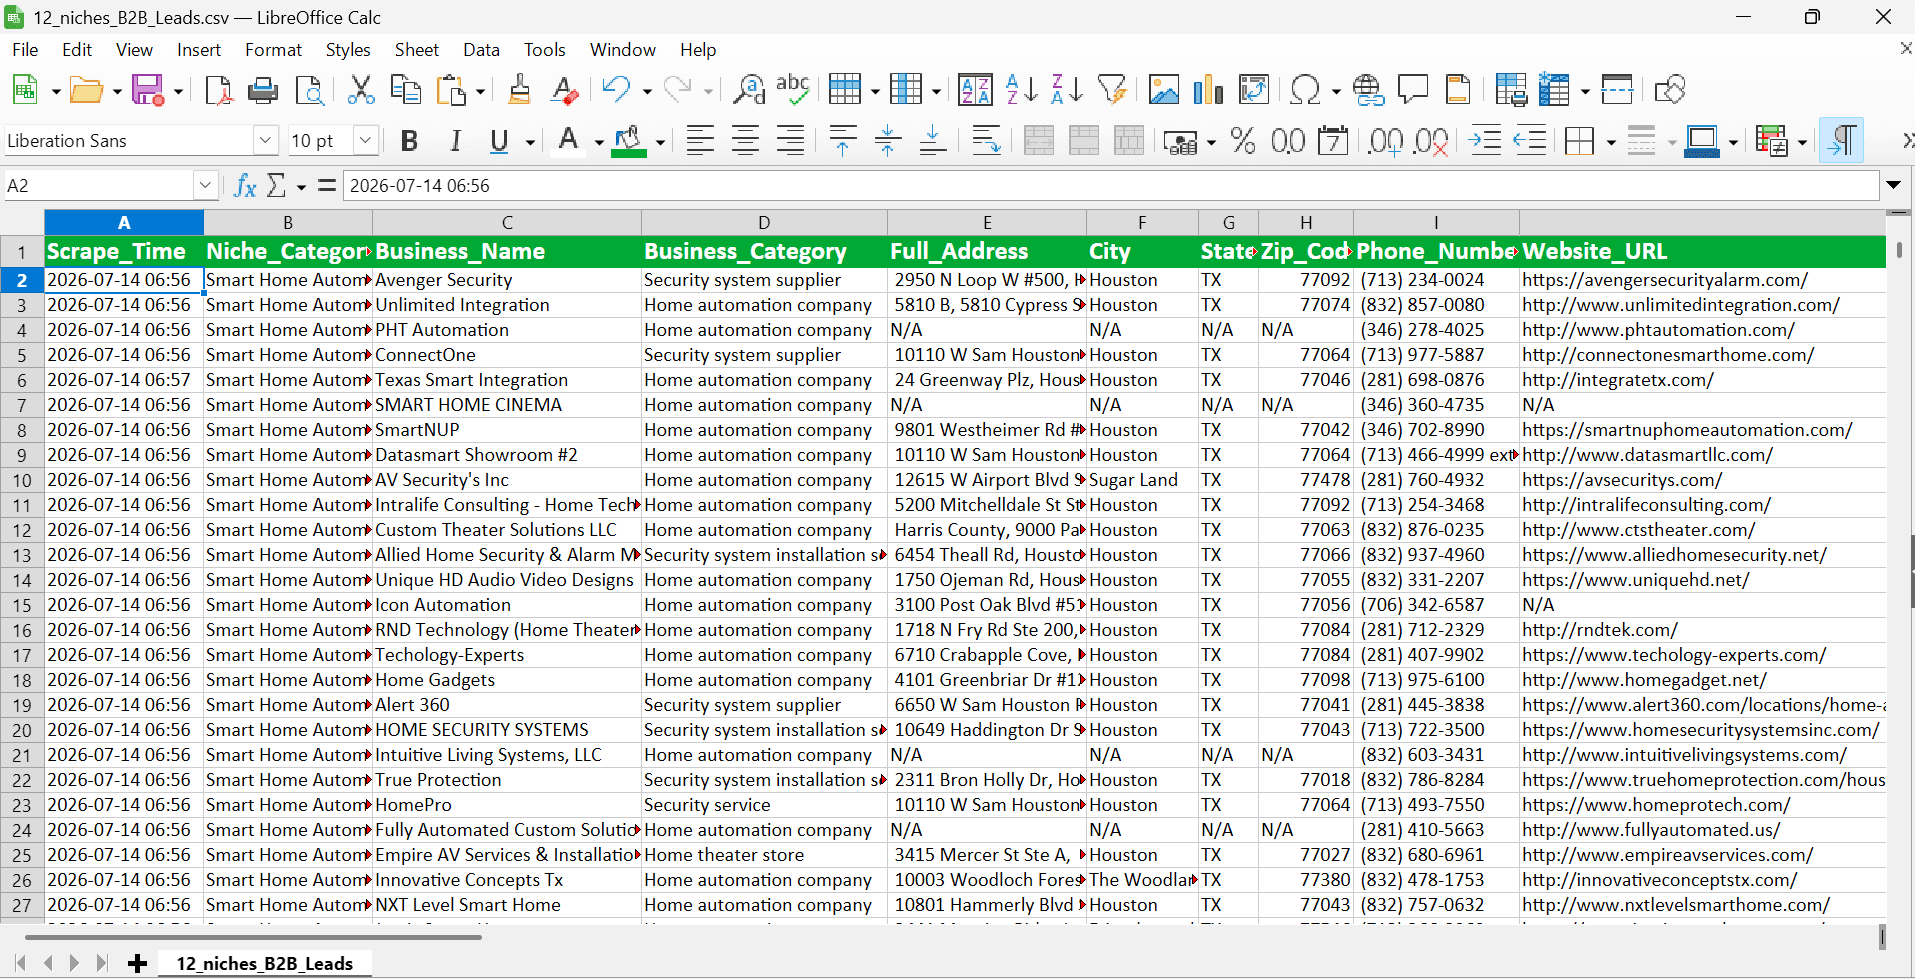
12 US niches, 186,662 verified leads

186,662 verified B2B records across 12 niches and 5,011 cities, with 27 enrichment fields and a chain blocklist.

186,662Verified leads
48%Email capture
27Fields
5,011Cities
PythonPlaywrightaiohttpPandas
Sample
US Healthcare Leads — Client Work project
Client Work
Project 112026

US Healthcare Leads

67,230 records across 50 states

67,230 dental, med-spa, chiropractic and veterinary records with MX-verified email and a quality score per row.

67,230Records
62.8%Scored 90+
98.9%Phone coverage
50States
PythonPlaywrightdnspythonPandas
Sample
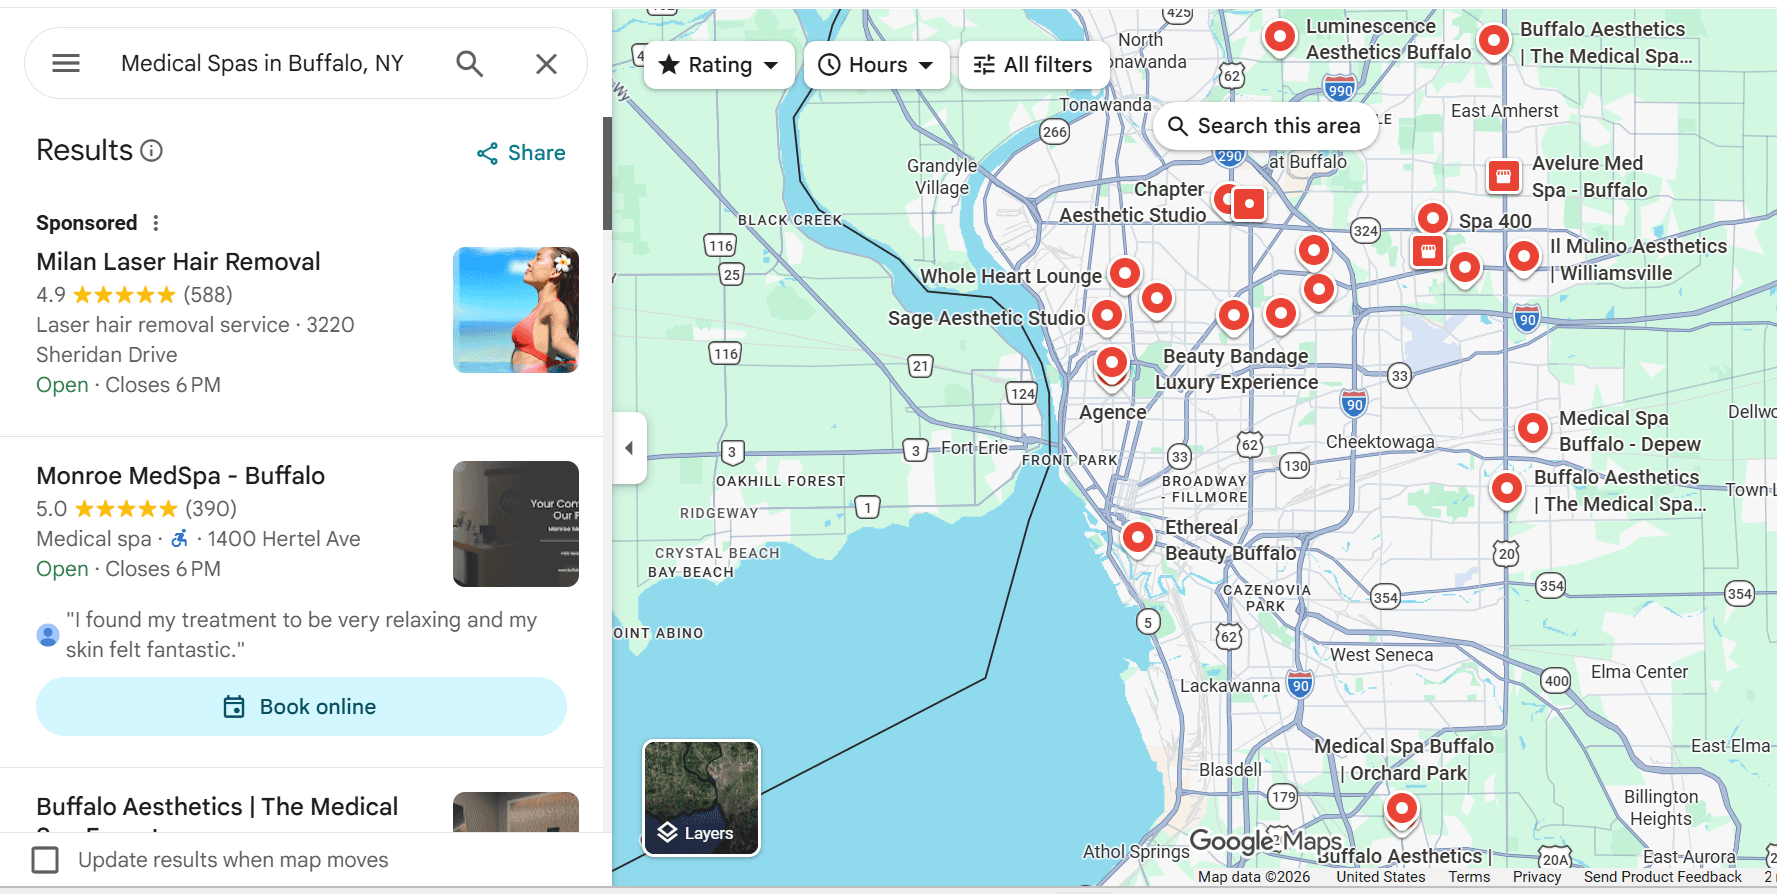
Medical Spa Lead Run — Client Work project
Client Work
Project 122026

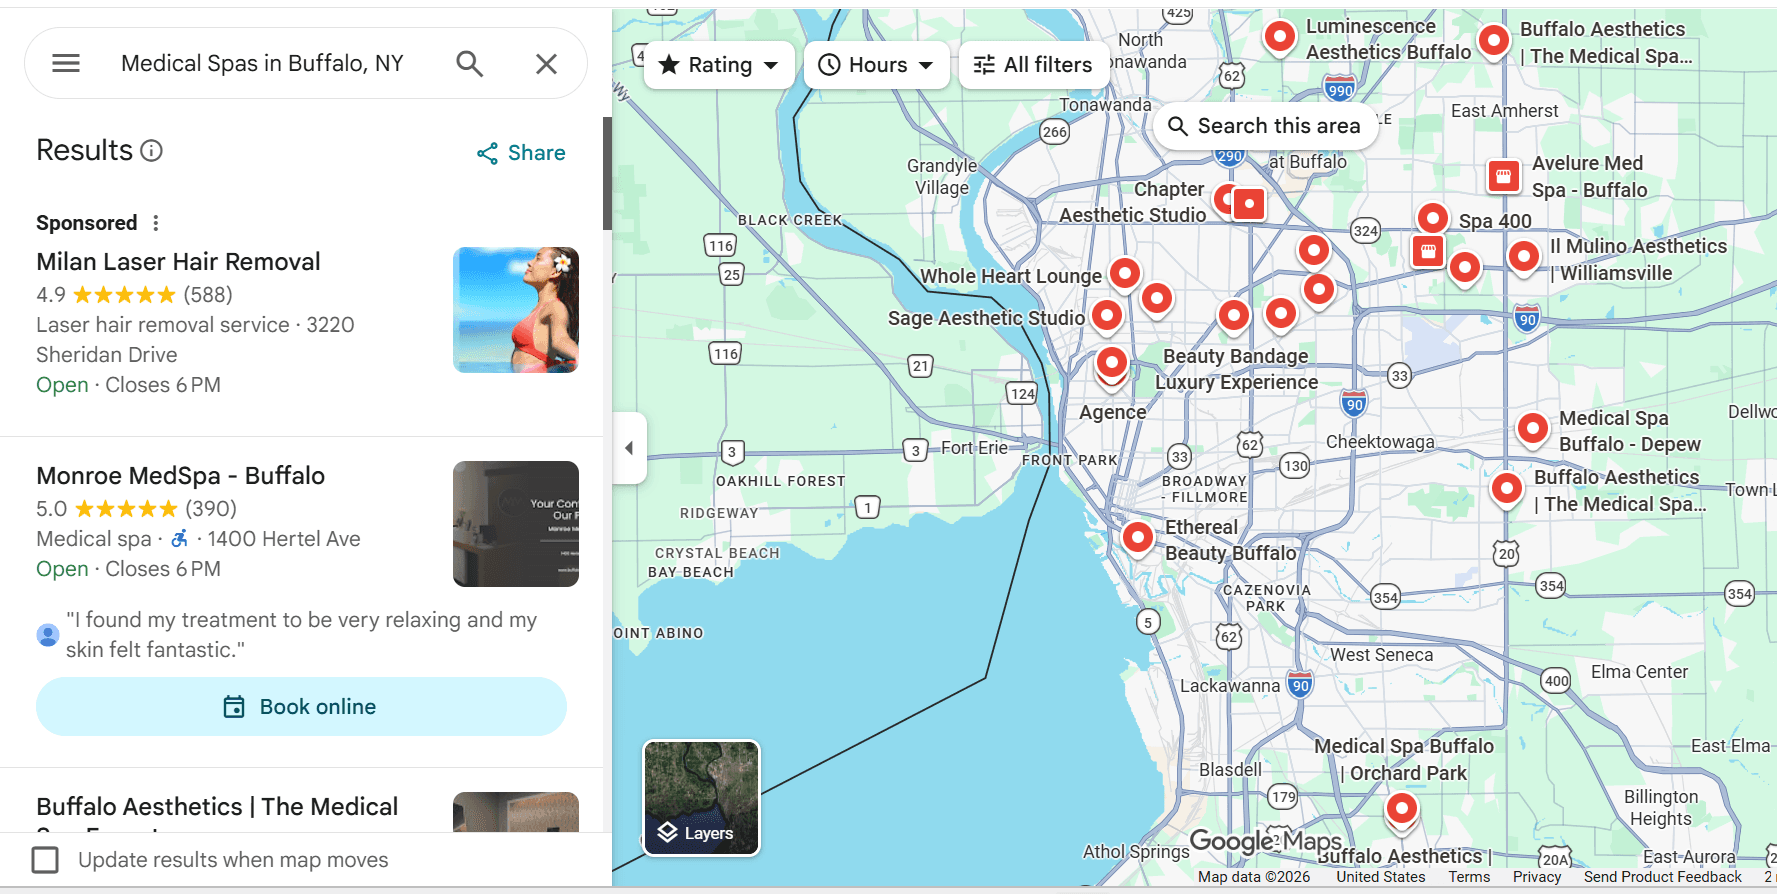
Medical Spa Lead Run

Buffalo NY clinics, Maps to spreadsheet

A single-market run: every medical spa in the Buffalo area, mapped, opened and turned into a contact spreadsheet.

1Market per run
3Sources merged
0Duplicate clinics
LiveMap coverage
PythonPlaywrightGoogle MapsPandas

03 — Stack

What I actually use.

Only tools I have shipped with.

38 tools
  • Python
  • SQL
  • HTML / CSS
  • Bash
  • Playwright
  • Scrapy
  • Selenium
  • Puppeteer
  • Postman
  • Pandas
  • NumPy
  • Jupyter
  • Postgres
  • SQLite
  • JSON / CSV
  • Google Sheets
  • Excel
  • Google Drive
  • Notion
  • Streamlit
  • Google Maps
  • LinkedIn
  • Apollo.io
  • Hunter
  • Skrapp
  • Prospeo
  • LeadSpace
  • SearchLeads
  • NeverBounce
  • Sales Navigator
  • Linux
  • Cron
  • Git
  • GitHub
  • Docker
  • FastAPI
  • DigitalOcean
  • Vercel

Drag, scroll sideways, or use the arrows

04 — Experience

Where I've worked.

Freelance Python Engineer
zaktecs.dev

Scrapers, pipelines and lead systems for agencies and founders.

Jun 2026 — Now
Data Scraper
ITEH Limited

Extraction jobs across multiple sources, with anti-bot handling and cleaning.

Mar — May 2026
Data Analyst
TEVTA Punjab

Consolidated survey data and rebuilt the recurring reporting trackers.

Nov 2025 — Jan 2026

05 — FAQ

The questions that come up first.

Anything else — email zakria@zaktecs.dev.

One to two weeks for a single site. Multi-source pipelines run three to six weeks.

Usually — real browser sessions, pacing and proxy rotation. Where terms forbid extraction, I'll say so.

The scraper breaks; that's normal. I keep maintenance retainers so selectors get repaired and alerts fire on empty runs.

Syntax, then DNS MX, then optional SMTP — plus dedupe and filters for disposable and role accounts.

Google Sheets, Excel, CSV, JSON or a database table — whatever fits how you already work.

06 — Contact

Send the link. I'll say if it's scrapable.

Tell me the site, the fields and the row count. You'll get a fixed price or a straight no.

  • ReplyWithin one working day
  • QuoteFixed price, before any work
  • Trial100 rows from one source, free
Email
zakria@zaktecs.dev
WhatsApp
+92 320 6825657
LinkedIn
/in/zakriashahbaz
GitHub
/zaktecs-ai
Location
Lahore, PK · GMT+5
Project brief
The more specific, the more accurate the quote.

Prefer email? zakria@zaktecs.dev